Kubeflow for Poets · Part 2 of 8
Introduction
27 March 2019Updated 14 October 20262 min read
This part shows that the learning algorithm is a small part of a machine learning production pipeline. It explains why containerized microservices on Google Cloud make the pipeline easier to reuse, scale and maintain.
Machine learning is often viewed as the use of mathematical algorithms to teach a computer tasks that are infeasible to program as a fixed set of instructions. From an engineering perspective, these algorithms make up only a small part of the overall learning pipeline. Building high-performing and dynamic learning models involves many other critical components. These components dominate the work of delivering an end-to-end machine learning product.
A typical machine learning production pipeline looks like the illustration below.
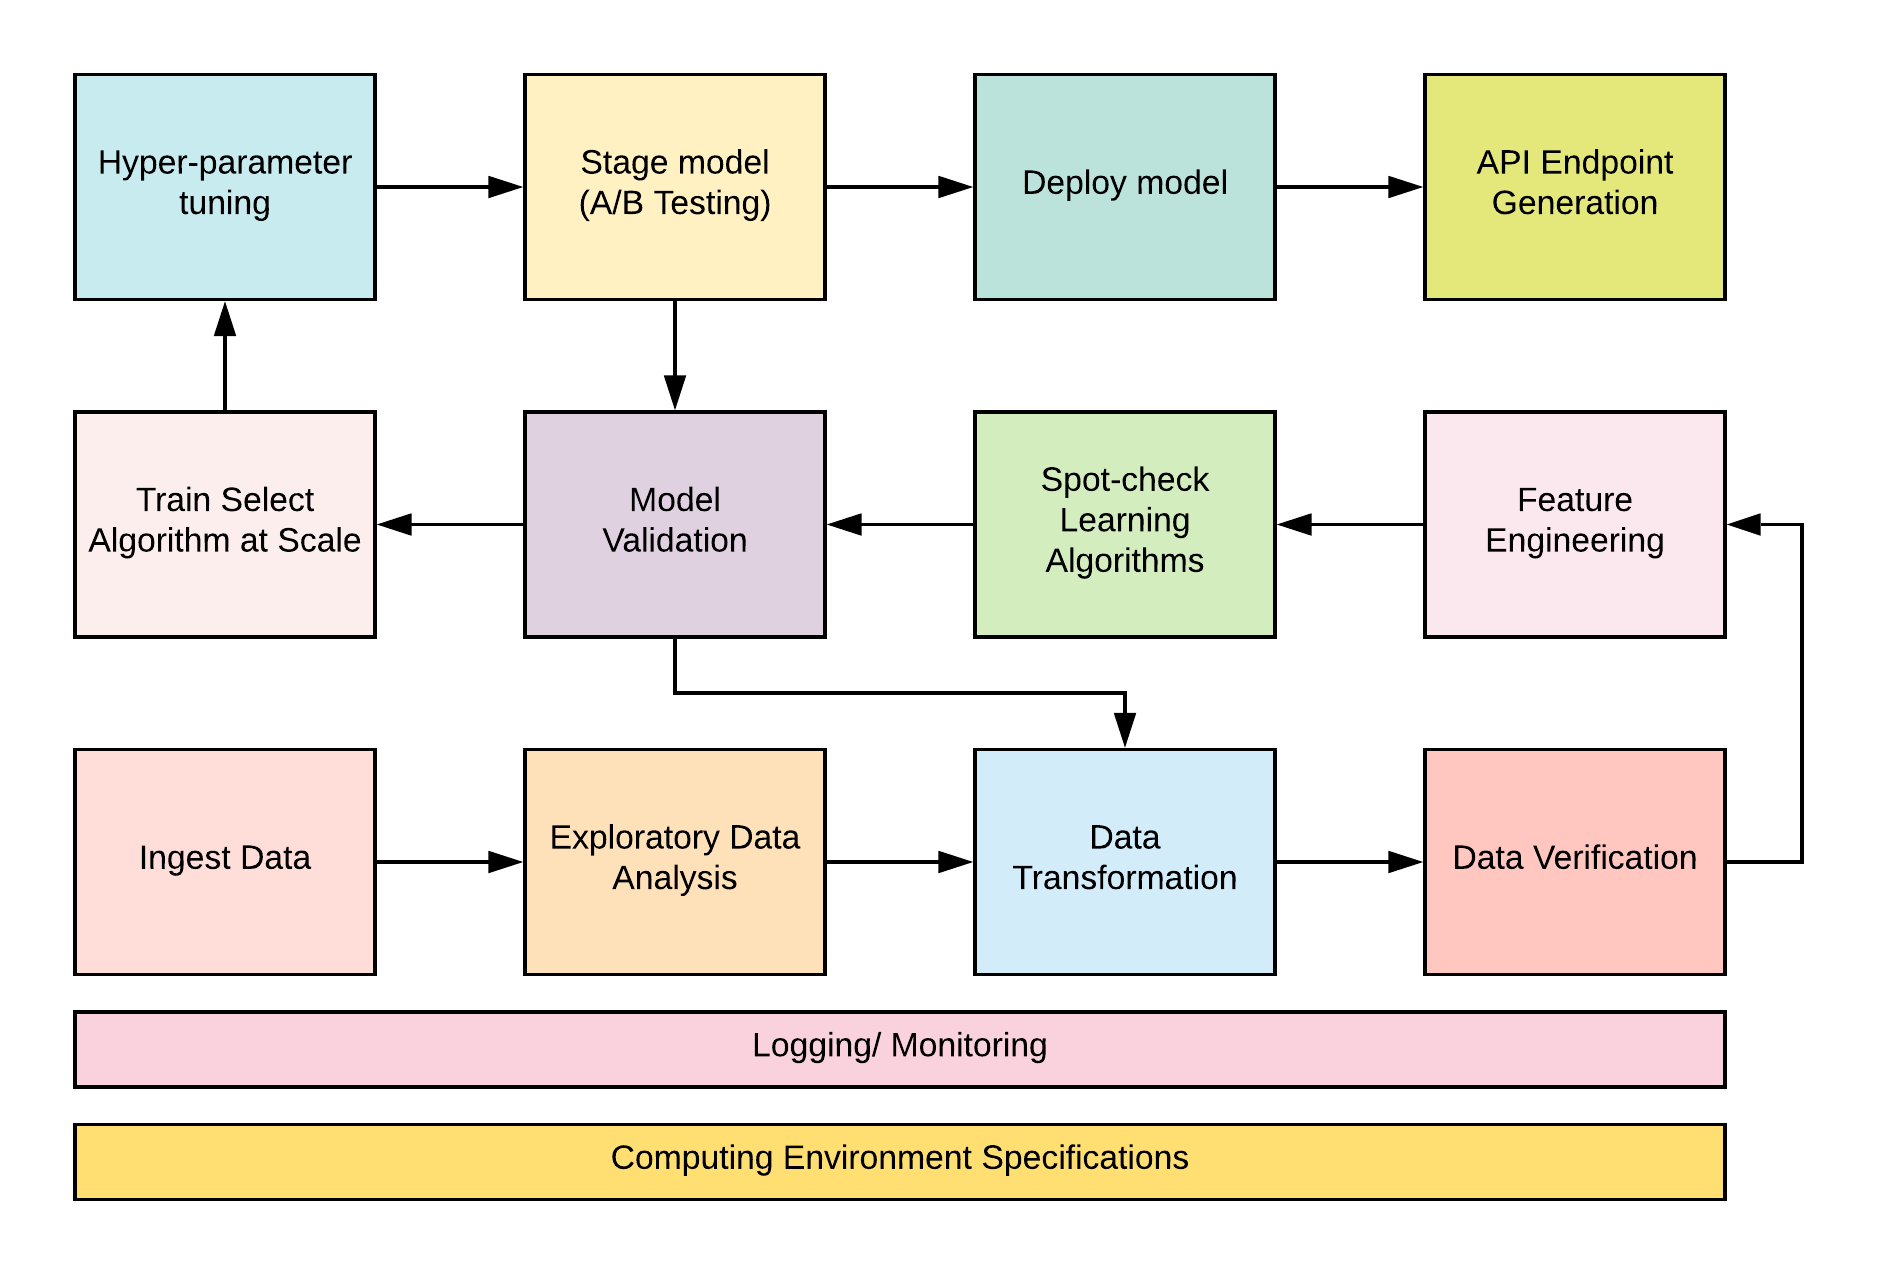
The diagram shows that the pipeline is iterative. Model validation feeds back into data transformation. This repeating pattern is central to machine learning experimentation, design and deployment.
The Efficiency Challenge
Moving a model smoothly from one component of the pipeline to the next takes a significant amount of development operations work. This need gave rise to Machine Learning Operations, also known as MLOps. The term combines machine learning and DevOps.
The conventional way of doing machine learning is to perform all experiments and development in Jupyter notebooks. The data scientist exports the trained model and hands it to a software development team. That team deploys the model and creates an endpoint that downstream software products can call. A DevOps team handles the infrastructure and machine configuration for model development. This monolithic way of working produces a machine learning process that is hard to reuse, scale, maintain and audit. It also makes model improvement slow and prone to errors.
We can address many of these concerns by applying the microservices design pattern to machine learning development. The next part explains this pattern.
A Word on Google Cloud
This series focuses on developing and deploying production models on Google Cloud. The cloud makes it easy to distribute individual workflow components and scale them out as resource demands change. A containerized pipeline is machine agnostic. You can also deploy it on your own infrastructure or on other public cloud providers such as AWS or Azure.
Google Cloud has managed services that we will use to handle some components of the production pipeline:
- BigQuery stages the transformed dataset for analytics.
- Dataflow runs large-scale data transformation.
- Gemini Enterprise Agent Platform trains and deploys models at scale.
The series first used Cloud Machine Learning Engine to train and deploy models. Google later renamed that service AI Platform, deprecated it and moved its features to Vertex AI. In April 2026, Vertex AI became part of Gemini Enterprise Agent Platform.
Ekaba Bisong is a Ph.D. researcher at the University of Victoria and the founder of SiliconBlast. More about me